Feanor designs and ships production AI on open-source models: private company assistants, video and image generation, voice, fine-tuning and self-hosted inference. Everything runs on hardware the client controls, at a cost that does not move with usage. This page is the capability map, written for partners.
One GPU box. Many models. Nothing leaves the building.
Every capability here runs on our own hardware today
Language modelsVideo generationImage generationVoice + speechFine-tuningAgentsOn hardware you own
Why open source, why now
The open models caught up.
For most business work, open-weight models now compete head-on with the big labs. What changed is not one model. It is the whole ecosystem: language, video, image and speech, all open, all improving monthly.
MONTHLY
New frontier drops, free to run
Llama, Qwen, DeepSeek and Mistral families ship new open-weight releases every few weeks. In video and image, models like LTX, Wan, Hunyuan and FLUX now rival closed systems. The progress arrives underneath what you own.
Open-weight release cadence, 2024 to 2026
5-20X
Cheaper at scale, and flat
Industry analyses put self-hosted inference at 5 to 20 times cheaper than metered APIs once usage is real. More important than cheap: the cost is flat. Your busiest month costs the same as your quietest.
Self-hosted LLM infrastructure analyses, 2026
IN-HOUSE
The only real privacy architecture
Legal, health and finance work cannot ship raw client data to a third-party API. Open weights run inside the building, on the client's hardware, with logs the client controls. Privacy as a fact, not a policy.
Regulated-industry deployment driver, 2026
The capability map
Six implementations we ship.
Each one is running in production today, on our own GPU infrastructure or on machines our clients keep. None of them depends on a metered API.
01
Private company assistants
A brain for the whole team: it answers on WhatsApp, Telegram, voice and a web dashboard, remembers every person, tracks tasks and meetings, and writes the company wiki as work happens. Routed across open-weight models by cost and skill.
SHIPPEDFour deployments of this pattern run in production today, serving operating teams in three countries.
02
Self-hosted inference infrastructure
One GPU machine, one private API, many models. We stand up the serving layer, the model registry and the access keys, so every app in the company talks to one endpoint and models swap in as better ones release. No meter, no data leaving.
STACK · GPU workstation or server · open serving engines · OpenAI-compatible gateway · per-app keys and budgets
SHIPPEDA 96 GB GPU box we run today serves chat, coding, image and video models behind one private API.
03
Fine-tuning and LoRA adapters
A general model becomes yours when it learns your domain. We train LoRA adapters on open models: a consistent brand character for every video, a house visual style, a language model that knows your products and writes like your company.
STACK · LoRA and IC-LoRA training on open checkpoints · dataset curation from your real material · evaluation before rollout
SHIPPEDIdentity adapters we trained keep the same presenter, face and wardrobe across entire marketing campaigns.
04
Video generation pipelines
Product reels, ads, explainers and training videos generated on our own GPUs with open video models. Control adapters (depth, pose, reference frames) make results repeatable, so a campaign holds one look instead of ten lucky accidents.
STACK · open video models (LTX, Wan, Hunyuan class) · control adapters · reference-frame workflows · edit and splice tooling
SHIPPEDA working reel pipeline goes from written brief to published social cut without a single API bill.
05
Image generation and editing
Marketing visuals, product shots, thumbnails and character sheets from open image models, plus in-house editing tools the team uses from a browser. Brand consistency comes from adapters and curated references, not from luck.
SHIPPEDAn internal image studio, generation plus editing, deployed as a one-click web app for daily use.
06
Voice, documents and verified answers
Transcription of calls and voice notes with open speech models, voice agents that answer and book around the clock, OCR over paper archives, and document Q&A that cites its sources. We built a citation-verification engine because an answer you cannot check is not an answer.
STACK · Whisper-class speech models · open TTS · OCR pipelines · retrieval with source citations · verification pass
SHIPPEDVoice notes from field teams are transcribed and filed automatically in production deployments today.
How an engagement runs
From workflow to working system.
We do not sell models. We sell working implementations of a business process, with the model as one part. The client ends up owning the whole thing.
01
Map the workflow
We sit with the real process: the quotes, the calls, the documents, the videos the business needs. The target is a workflow, never "add AI".
02
Pick models and hardware
Open models are picked by test, not fashion, and sized to hardware the budget supports: one workstation for a team, a server for a company.
03
Build and integrate
We build the pipeline, wire it into the tools the team already uses, and prove it on the client's real material before anyone calls it done.
04
Hand over the keys
The client owns the hardware, the weights and the data. We stay for upkeep and model upgrades, or train the team to run it alone.
Who builds it
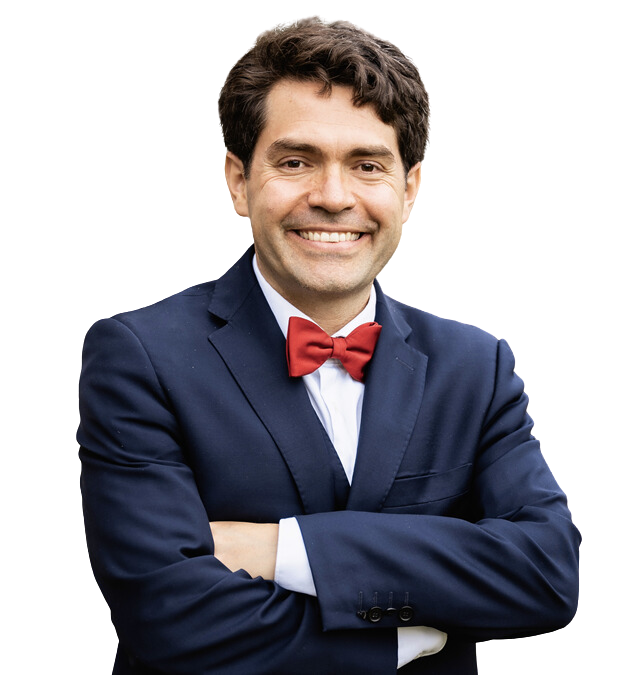
Francisco Cordoba Otalora
FOUNDER, FEANOR · MIT INNOVATOR UNDER 35 · MARIE CURIE FELLOW
Francisco has spent 15 years building technology companies and teaching. He was named an MIT Technology Review Innovator Under 35 in 2018, wrote "Beat the Humans" on the future of work with AI, and has spoken on emerging technology at Google I/O, NFT NYC, Imperial College London and the World Economic Forum.
Today he is a Marie Curie Research Fellow publishing peer-reviewed research, and he builds and runs production AI agents for entrepreneurs, ministers' offices, and operating teams across three continents. Feanor is where that work becomes a service: open-source AI, implemented and handed over.
"Every business will run on AI. The only question is whether you'll own yours, or rent it forever."
MIT Innovator Under 35Marie Curie Research FellowAuthor, Beat the HumansVisiting professor, Singularity UniversityProduction AI on 3 continents
Partnering
Who we want to build with.
We bring the open-source delivery arm. You bring the clients, the hardware, or the vertical.
Feanor is a small, senior operation. We are not looking for many partners. We are looking for the right three.
Agencies and consultancies
You sell AI transformation. We build and run the open-source implementations behind it, white-label or side by side.
Companies with distribution
You already serve SMBs or professional firms. Private assistants, media pipelines and fine-tuned models become products in your catalog.
Hardware and hosting providers
You ship GPUs, workstations or racks. We make them do something a buyer can see: a working AI system on the machine, day one.